 Web Scraper API
 Google Shopping API
 Google Search API
 Google Maps API
 ChatGPT API
 Glassdoor API
 Trustpilot API
 Crunchbase API
 YouTube API
 TikTok API
 Instagram API
 Google News API
 Reuters API
 Bloomberg API
 Associated Press API
News corpus for research and RAG
Kaan Ersoy1 min read
Who runs this, and what for
| Team | What they decide with it |
|---|---|
| Researchers | How a topic was covered over a period, from the text rather than the headlines. |
| AI engineers | What current, sourced text to put in a retrieval index so a model can cite news. |
| Analysts | Which events and entities recur in coverage of a market or region. |
The calls, step by step
1. Associated Press world news
GET /v1/ap/search
2. Associated Press article
GET /v1/ap/article
1. Search the topic
AP search takes q with sort=newest and up to 20 pages. Each result has the URL, publish time, and content type; keep articles and skip videos and galleries.
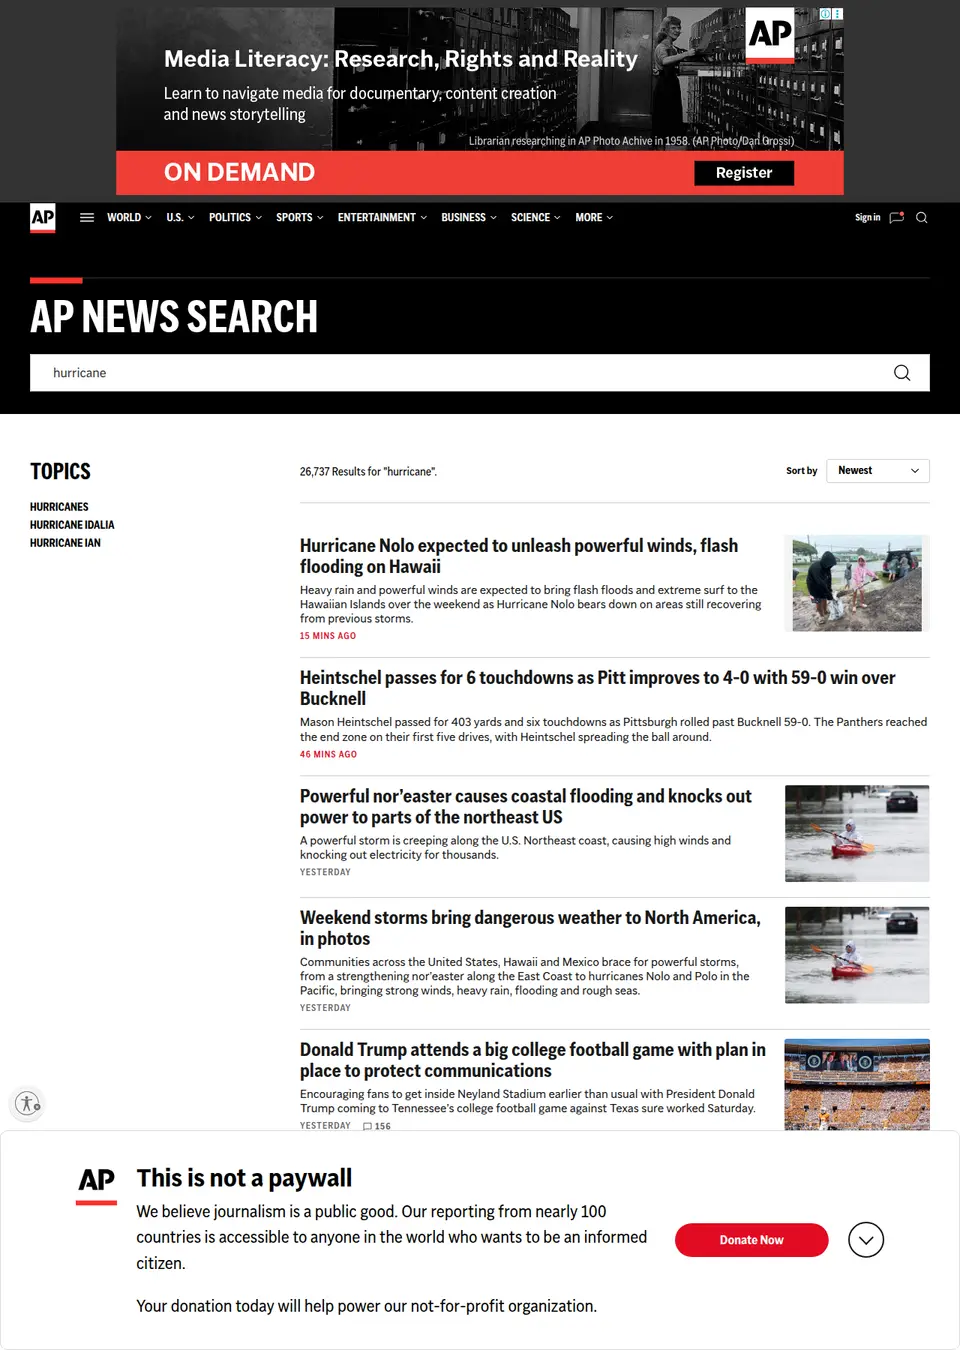
The page on apnews.com that this call reads, as a signed-out visitor sees it. The response below is what Clair returns from it. GET /v1/ap/search?q=hurricane&sort=newest&page=1 · results.0
{
  "position": 1,
  "title": "Powerful Hurricane Polo drenches Mexico’s coast as Nolo takes aim at Hawaii",
  "url": "https://apnews.com/article/hurricane-polo-mexico-nolo-hawaii-a036e08f59c3f3842aaba2ee69bd9d37",
  "published_at": "2026-09-24T08:20:28.000Z",
  "authors": [],
  "content_type": "article",
  "premium": false
}
Recorded response. Live values differ. 2. Read each article
The article endpoint returns the story as paragraphs, with authors and section. AP stories are free to read, so body_truncated is false and the text is complete.
GET /v1/ap/article?url=https%3A%2F%2Fapnews.com%2Farticle%2Fhurricane-polo-mexico-nolo-hawaii-a036e08f59c3f3842aaba2ee69bd9d37 · article
{
  "title": "Powerful Hurricane Polo drenches Mexico’s coast as Nolo takes aim at Hawaii",
  "url": "https://apnews.com/article/hurricane-polo-mexico-nolo-hawaii-a036e08f59c3f3842aaba2ee69bd9d37",
  "authors": [
    {
      "name": "Desiree Brooks",
      "url": null
    },
    {
      "name": "Megan Janetsky",
      "url": null
    }
  ],
  "section": "World News",
  "access": "free",
  "body_truncated": false,
  "paragraphs": [
    "Hurricane Polo dumped heavy rain on Mexico’s Pacific coast."
  ]
}
Recorded response. Live values differ. 3. Store it with its source
Keep the URL and publish time with every document. A retrieval system that cites the article, with its date, is one readers can check.
GET /v1/ap/article?url=https%3A%2F%2Fapnews.com%2Farticle%2Fhurricane-polo-mexico-nolo-hawaii-a036e08f59c3f3842aaba2ee69bd9d37 · article.url
"https://apnews.com/article/hurricane-polo-mexico-nolo-hawaii-a036e08f59c3f3842aaba2ee69bd9d37"Recorded response. Live values differ.
A script to start from
news_corpus.py
# Build a news corpus for a topic from AP: search, then read each article,
# and write one JSON line per story for analysis or a retrieval index.
import json, os, requests

API = "https://api.clair.im"
HEADERS = {"Authorization": f"Bearer {os.environ['CLAIR_API_KEY']}"}
QUERY = "hurricane"
PAGES = 5

def get(path, **params):
    r = requests.get(f"{API}{path}", headers=HEADERS, timeout=60, params=params)
    r.raise_for_status()
    return r.json()

urls = []
for page in range(1, PAGES + 1):
    body = get("/v1/ap/search", q=QUERY, sort="newest", page=page)
    urls += [r["url"] for r in body["results"] if r["content_type"] == "article"]
    if not body["next_cursor"]:
        break

with open("corpus.jsonl", "w") as f:
    for url in dict.fromkeys(urls):  # keep order, drop repeats
        a = get("/v1/ap/article", url=url)["article"]
        f.write(json.dumps({
            "url": a["url"], "title": a["title"], "section": a["section"],
            "authors": [x["name"] for x in a["authors"]],
            "text": "\n\n".join(a["paragraphs"]),
        }) + "\n")
Set CLAIR_API_KEY to your Clair key; one plan covers the Associated Press API. Each call spends that API's rate from the plan's monthly balance.
What it costs per month
| Schedule | Requests | Plan | Per month | Per 1,000 |
|---|---|---|---|---|
| One topic, 100 articles5 search pages plus 100 article calls = 105 requests. | 105 | Starter | $30 | $285.71 |
| 10 topics, 200 articles each10 × (10 search pages + 200 articles) = 2,100 requests. | 2,100 | Starter | $30 | $14.29 |
| Daily top-up: 30 new articles a dayOne search page and 30 articles a day for 30 days = 930 requests. | 930 | Starter | $30 | $32.26 |
What to plan for
- Rights stay with AP. Analysis, research, and retrieval with citations are the usual uses; republishing stories needs an AP license.
- AP search goes back as far as AP's site search does, up to 20 pages per query. For longer periods, run narrower queries.
- Section and topic hub pages mix in most-read and right-rail cards. Search results are cleaner for a corpus.
Common questions
Can I use Reuters or Bloomberg the same way?
Yes, with limits. Reuters has no keyword search, so list sections or authors. Bloomberg search works, but metered stories return only their public paragraphs.
What format should the corpus be?
JSON lines, one story per line with url, title, date, and text, loads into most analysis and embedding tools without conversion.
How do I avoid duplicates?
Deduplicate on the article URL. AP updates stories in place, so re-reading a URL later gives the latest version.