 Web Scraper API
 Google Shopping API
 Google Search API
 Google Maps API
 ChatGPT API
 Glassdoor API
 Trustpilot API
 Crunchbase API
 YouTube API
 TikTok API
 Instagram API
 Google News API
 Reuters API
 Bloomberg API
 Associated Press API
Content research from People also ask
Kaan Ersoy1 min read
Who runs this, and what for
| Team | What they decide with it |
|---|---|
| Content and SEO teams | Which articles to write next, and which questions each should answer. |
| Product marketers | What buyers ask about a category before they compare products. |
| Support teams | Which questions to answer in public documentation before customers ask. |
The calls, step by step
1. Search the seed topics
Search each topic with the country and language you write for. People also ask and related searches are on the first page, so one page per query is enough.
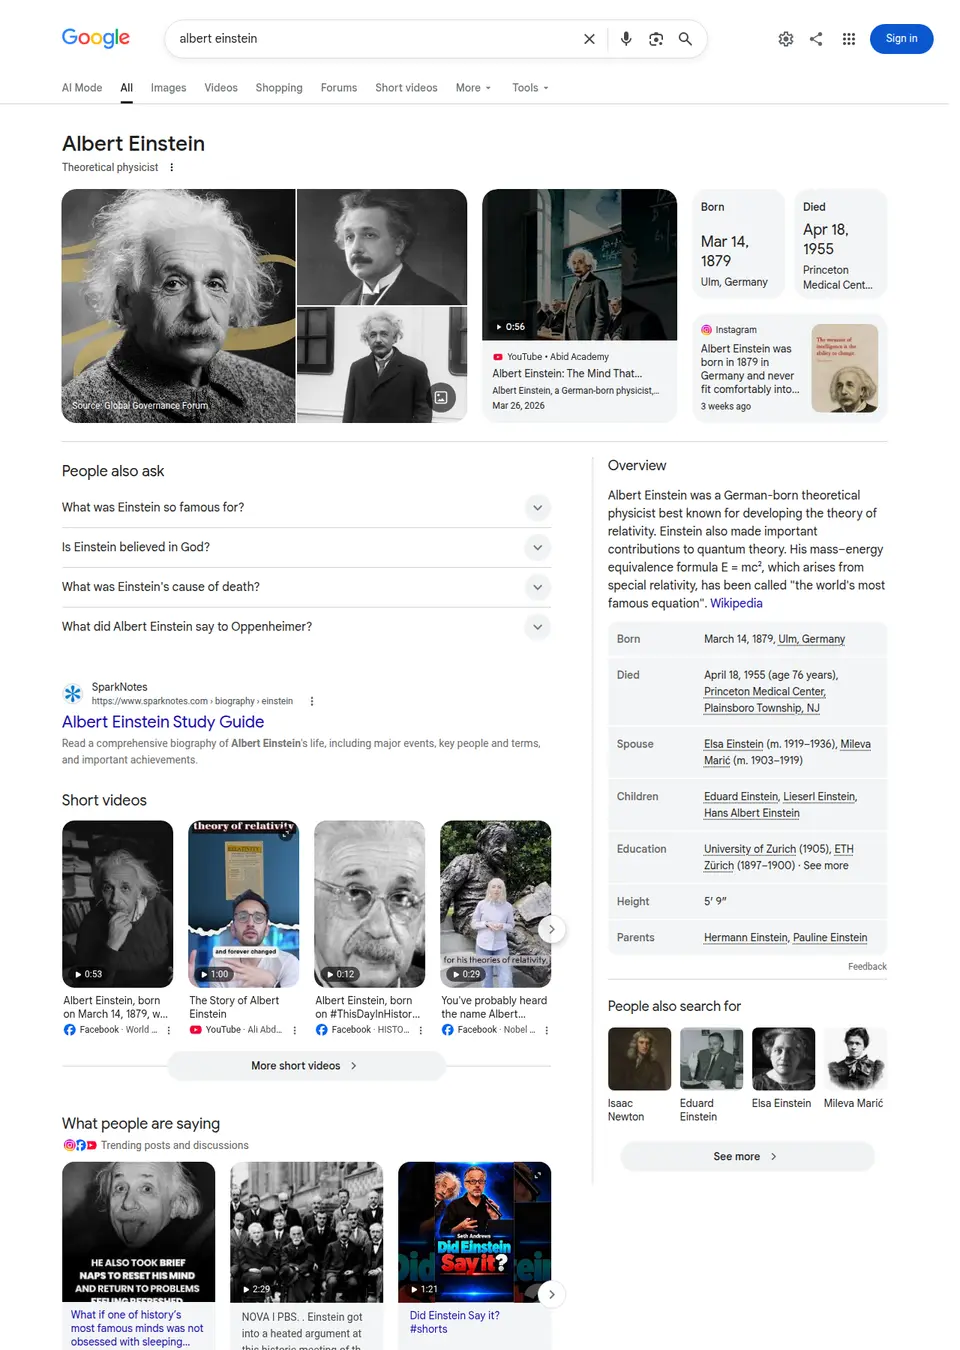
The page on google.com that this call reads, as a signed-out visitor sees it. The response below is what Clair returns from it. GET /v1/google-search?q=albert+einstein&country=us&page=1 · query
{
  "q": "albert einstein",
  "language": "en",
  "country": "us",
  "page": 1
}
Recorded response. Live values differ. 2. Keep the questions
people_also_ask lists the questions Google showed. These are phrased the way people ask, which makes them good headings and FAQ entries.
GET /v1/google-search?q=albert+einstein&country=us&page=1 · people_also_ask
[
  "What is Einstein famous for?",
  "Did Einstein believe in God?"
]
Recorded response. Live values differ. 3. Follow related searches one level
related_searches are the queries people type next. Search the first few of them to widen the map without it growing out of hand.
GET /v1/google-search?q=albert+einstein&country=us&page=1 · related_searches
[
  "Albert Einstein quotes",
  "Albert Einstein inventions"
]
Recorded response. Live values differ.
A script to start from
content_research.py
# Map what searchers ask around a topic: People also ask and related
# searches for seed queries, expanded one level. Out: questions.csv.
import csv, os, requests

API = "https://api.clair.im"
HEADERS = {"Authorization": f"Bearer {os.environ['CLAIR_API_KEY']}"}
SEEDS = ["web scraping api", "serp api", "amazon price tracker"]

def serp(q):
    r = requests.get(f"{API}/v1/google-search", headers=HEADERS, timeout=60, params={
        "q": q, "country": "us", "language": "en"})
    r.raise_for_status()
    return r.json()

rows, done = [], set()
for seed in SEEDS:
    body = serp(seed)
    done.add(seed)
    rows += [(seed, "question", q) for q in body["people_also_ask"]]
    rows += [(seed, "related", q) for q in body["related_searches"]]
    # One level deeper: related searches are queries people type next.
    for q in body["related_searches"][:5]:
        if q in done:
            continue
        done.add(q)
        rows += [(q, "question", x) for x in serp(q)["people_also_ask"]]

with open("questions.csv", "w", newline="") as f:
    csv.writer(f).writerows([("from_query", "kind", "text"), *dict.fromkeys(rows)])
Set CLAIR_API_KEY to your Clair key; one plan covers the Google Search API. Each call spends that API's rate from the plan's monthly balance.
What it costs per month
| Schedule | Requests | Plan | Per month | Per 1,000 |
|---|---|---|---|---|
| 20 seed topics, one level deep20 seeds plus 5 related searches each = 120 requests. | 120 | Starter | $30 | $250 |
| 200 seed topics, one level deep200 × 6 = 1,200 requests. | 1,200 | Starter | $30 | $25 |
| 200 topics in 5 markets, monthly refresh1,200 × 5 markets = 6,000 requests. | 6,000 | Starter | $30 | $5 |
Response times
| Google Search API | |
|---|---|
| Succeeded | 18 of 20 |
| Median response time | 6.2 s |
| 95th percentile | 25.2 s |
| Had knowledge graph | 28% |
| Had people also ask | 94% |
| Had related searches | 78% |
| Had local results | 11% |
| Had videos | 33% |
What to plan for
- People also ask returns the questions shown when the page loads. Google adds more as a visitor opens them; those are not returned.
- Answers to the questions are not included. Search the question itself to see which pages answer it.
- Not every query shows these blocks. Brand and navigational queries often have neither.
Common questions
Does it return search volume?
No. Google Search results do not include volume. Use a keyword tool for volume and this for the questions.
How often do the questions change?
Slowly for most topics. A monthly or quarterly refresh is enough, except in fast-moving subjects.
Can I run this for other countries?
Yes. Pass country and language; the questions differ by market even in the same language.